Benchmarks
- [nips 2026] CineMME: Benchmarking Fine-Grained Perception and Plot Reasoning in Multimodal Large Language Models
- [] Visual Reasoning Benchmark: Evaluating Multimodal LLMs on Classroom-Authentic Visual Problems from Primary Education
Surveys
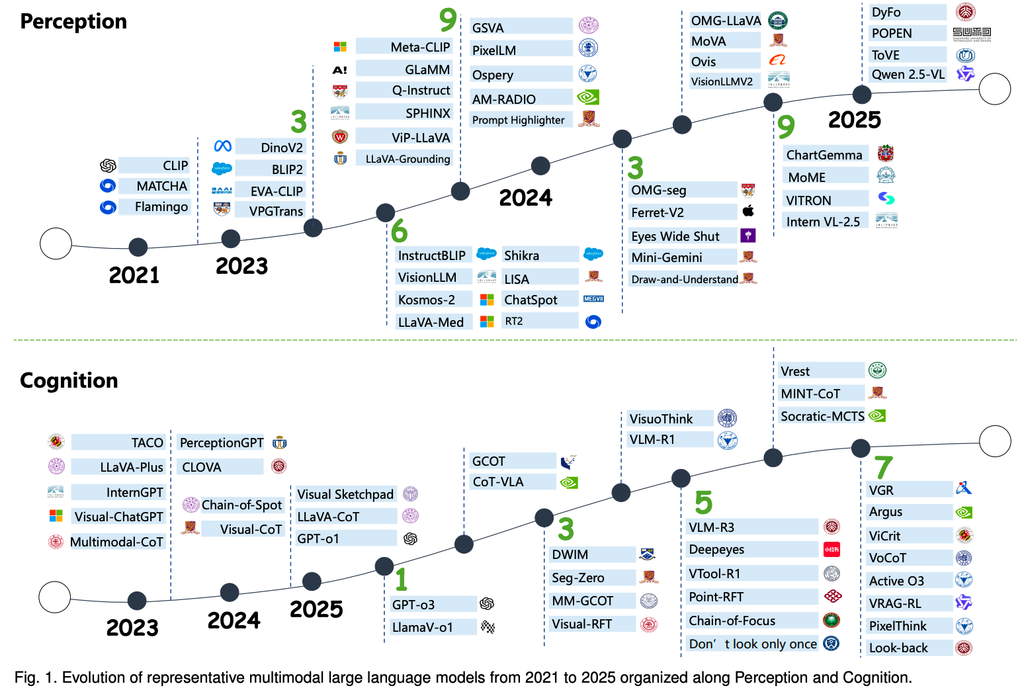
- [202510] From Perception to Cognition: A Survey of Vision-Language Interactive Reasoning in Multimodal Large Language Models https://arxiv.org/pdf/2509.25373v3
- Perception:
- Coarse-grained alignment at the perception level (CLIP这一路的模型缺少对图片局部区域,精细化的图文对齐)
- Cognition:
- 模型的对于问题的分解能力;
- 缓和模型在推理过程中的幻觉问题;(因为模型大多是一次读取图片,基于读取图片的内容再进行分析,缺少了逐步深入的过程)
- Perception:
沿着这两点对大模型进行分类如下:
Perception
- [NeurIPS 2025 poster] Perception-R1:https://neurips.cc/virtual/2025/loc/san-diego/poster/119361
- [NeurIPS 2025 poster] ViCrit:A Verifiable RL proxy Task for Visual Perception in VLMs https://openreview.net/pdf?id=j42rziWq1n
- UFO: A Unified Approach to Fine-grained Visual Perception via Open-ended Language Interface https://neurips.cc/virtual/2025/loc/san-diego/poster/119594
- [Nips 2026] C2FT: Enhancing Fine-Grained Perception in MLLMs via Confuse-then-Contrast Fine-Tuning
- paper 没有给出来
- C2FT这个概念还挺热门……
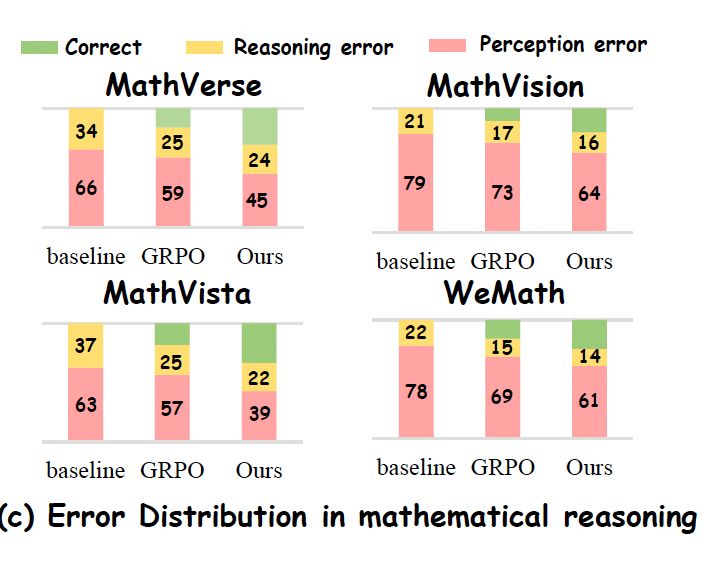
- UniCAR-RL: Seeing Better before Thinking Deeper in Visual Mathmatics https://arxiv.org/pdf/2609.13849
UniCAR-RL
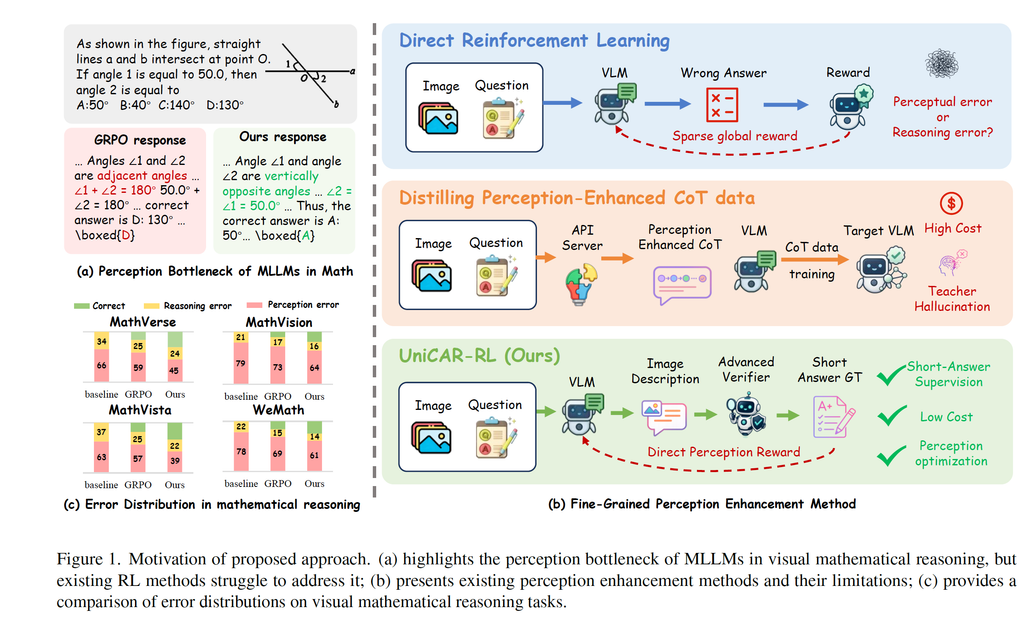
- 要解决什么问题?
- fine-grained perception 差;
- 为了Perception蒸馏 teacher 的cot数据是耗时耗钱;
- 怎么解决的问题?
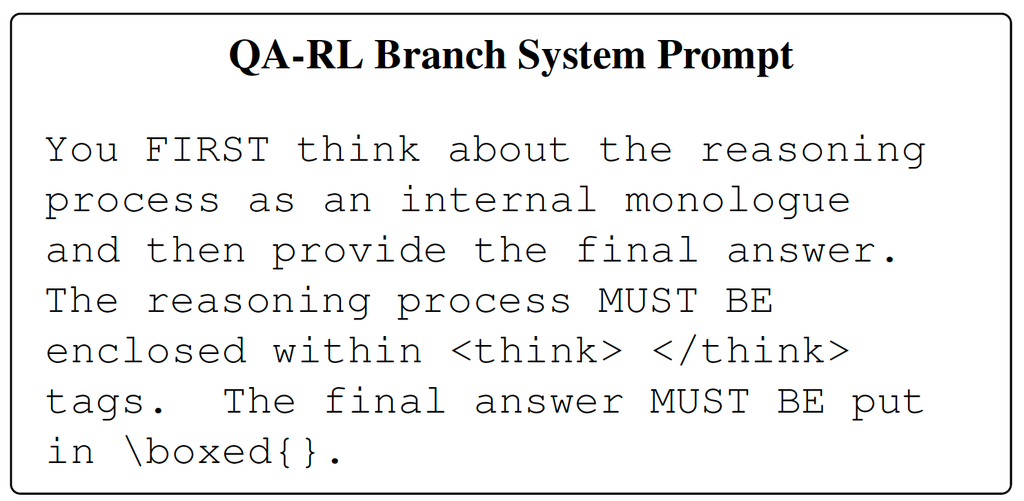
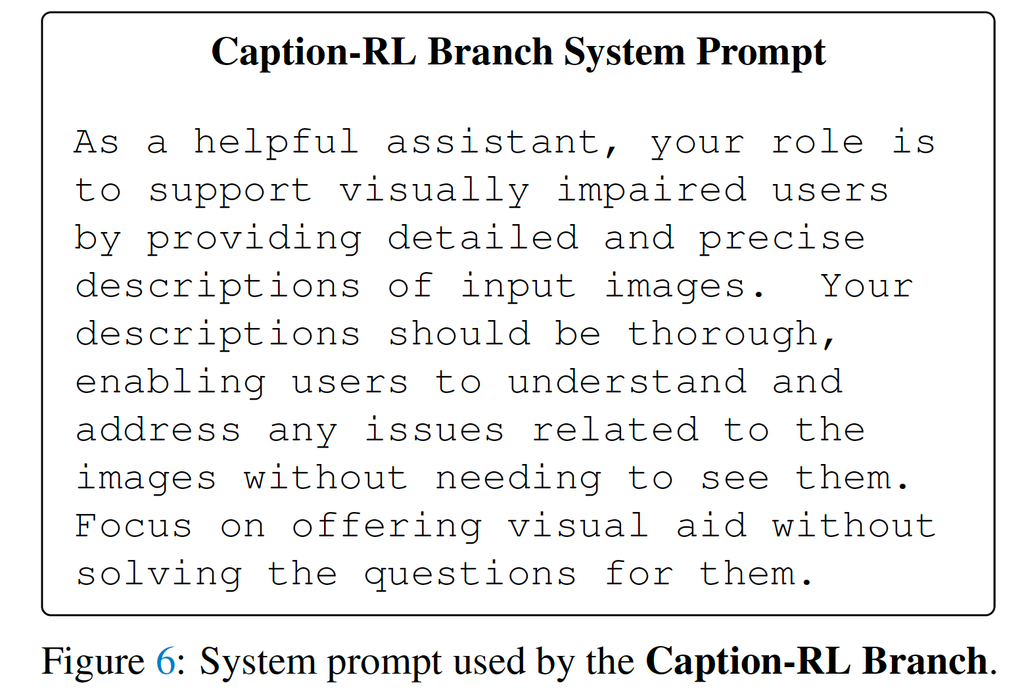
- 根据RL的思想,分别从三处使用RL,进而提升模型的感知能力、推理能力、端到端地回答能力;
- 问题解决地效果如何?
- 在数学和视觉推理方向有一定提升;
模型架构
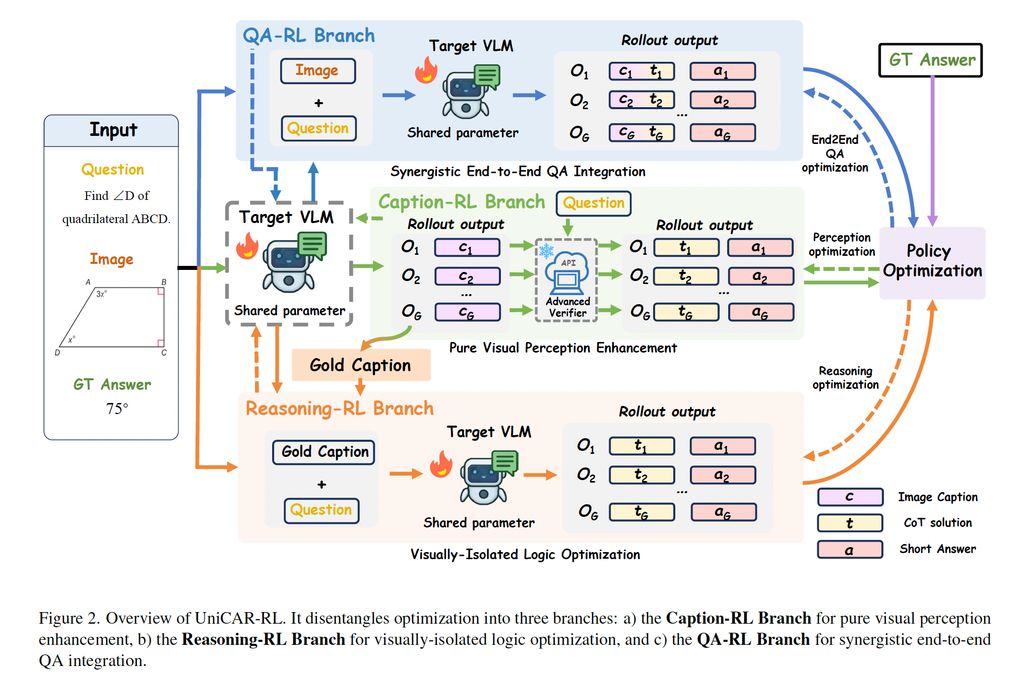
用一个简单的例子来说明训练的过程:
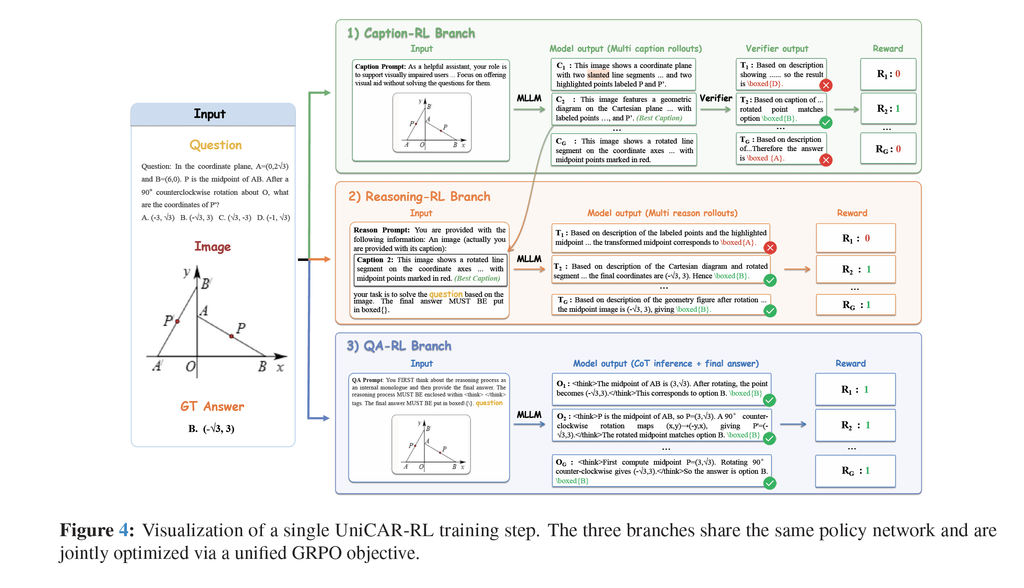
- 使用三个RL来优化模型,包括:caption-RL/Reasoning-RL/QA-RL
- Caption-RL 中的Verifier 是指用具体的哪个
方法简介
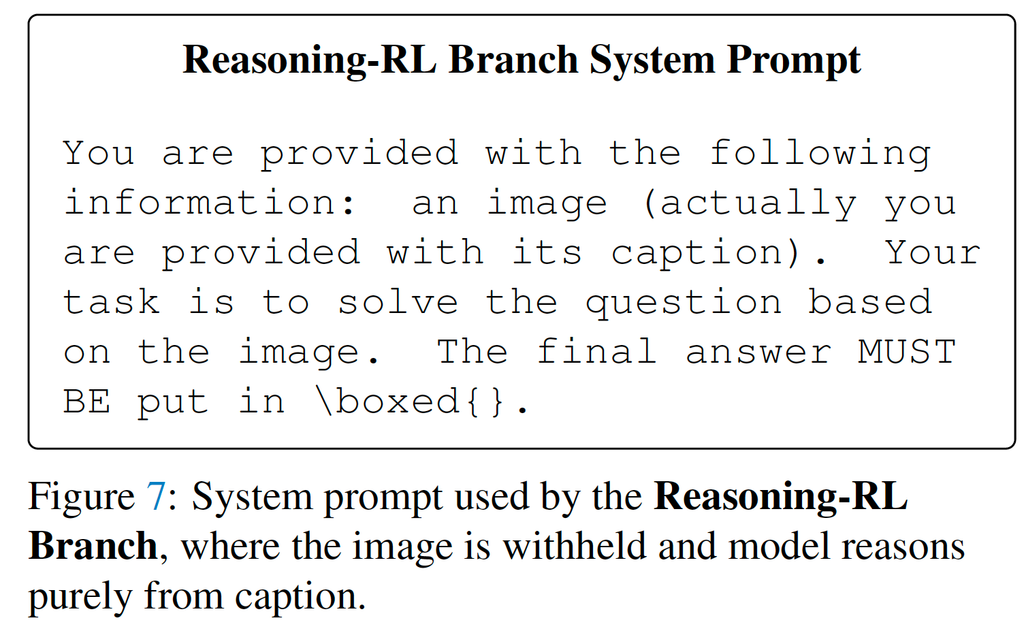
Reasoning
- (2026 Nips) Structure Over Scale: Learning Visual Reasoning from Pedagogical Video: https://arxiv.org/abs/2601.23251
Structure over Scale
挑这篇论文的原因:
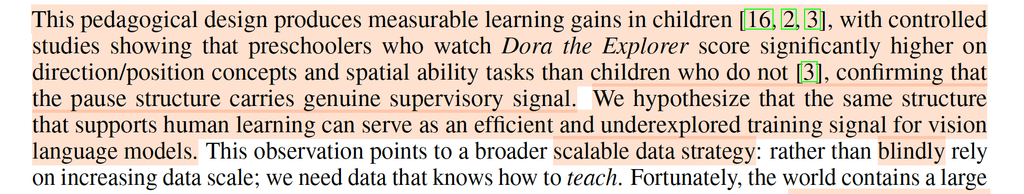
- 跟教育息息相关(幼儿的教育视频会极大地提升幼儿的推理能力)
- 如何从已有的数据中构造出数据?
模型流程
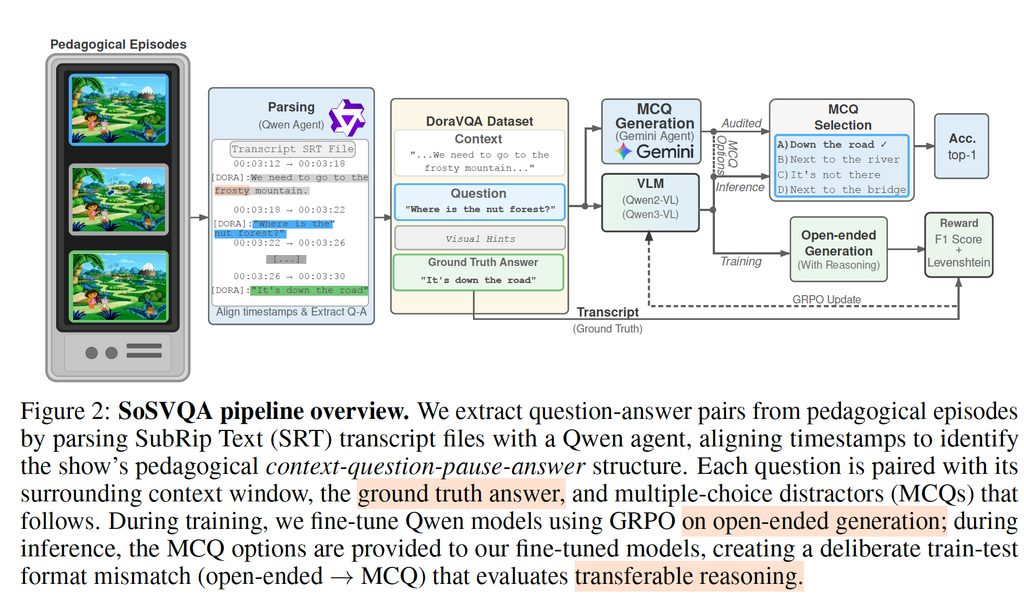
三个步骤:
- 使用Qwen Agent 从SRT文件获取结构化数据;
- 训练:生成open-ended 的结果,使用GRPO的方式来优化;
- 推理:使用MCQ的方式来推理(测试模型的效果)
模型效果分析
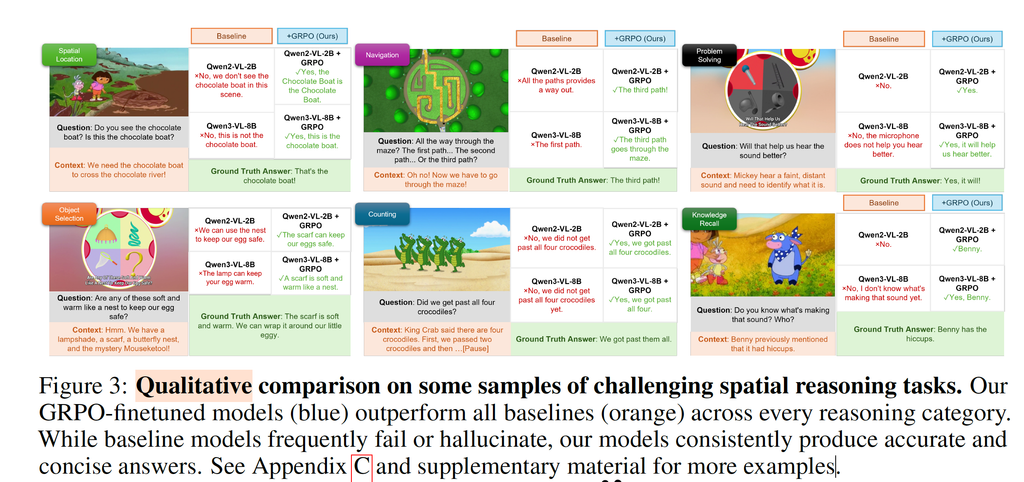
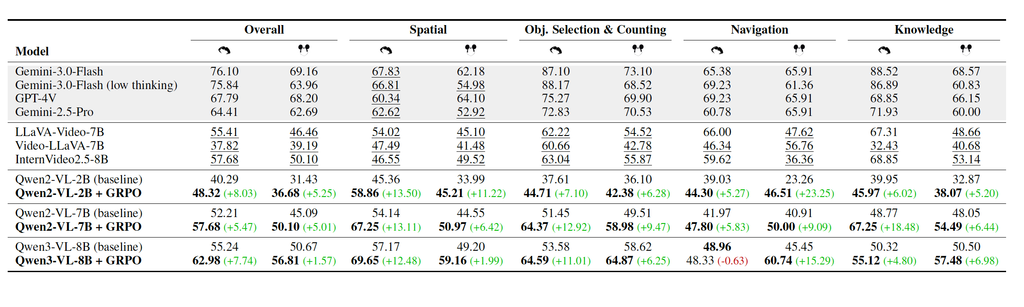
不过有一个问题是:这里的测试case应该是来自于DoraVQA ? 而这个模型又是在这个数据集上做的微调,那在这个数据集上的效果肯定要比其它模型好不应该是正常的吗?
消融实验
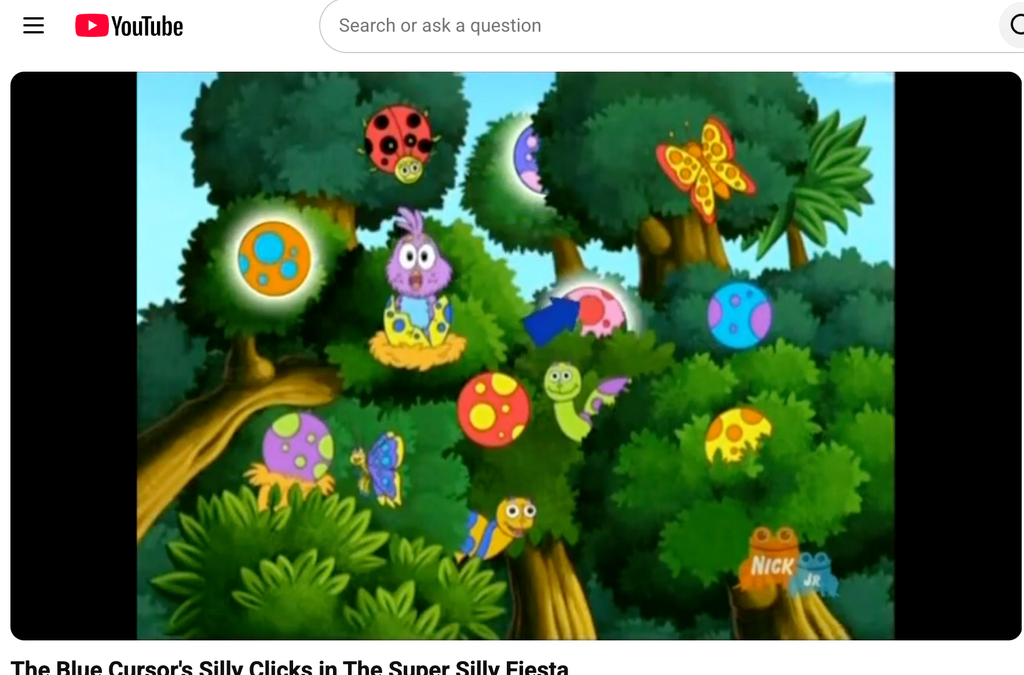
Pause(hint)的作用有多大?
这里的pause其实就是图(视频帧)中给予的提示。如下所示:
作者做了不同等级的提升实验,用于观察hint是否真的有效。实验分成四个等级:
- No-Hint:不给提示;
- Self-localized:模型自己定位。第一轮infer,让模型自己给出arrow的bounding box;第二轮infer,基于第一轮的结果拿到预测结果;
- Prompted hint:给出了一段关注箭头内容的提示:(“Locate the blue arrow in the image. Use its bounding-box coordinates to identify the object or region it is pointing at, and use that information to answer the question.”)
- Oracle box:给出了答案所指向物体的bounding box;
针对上述三项的实验结果如下:
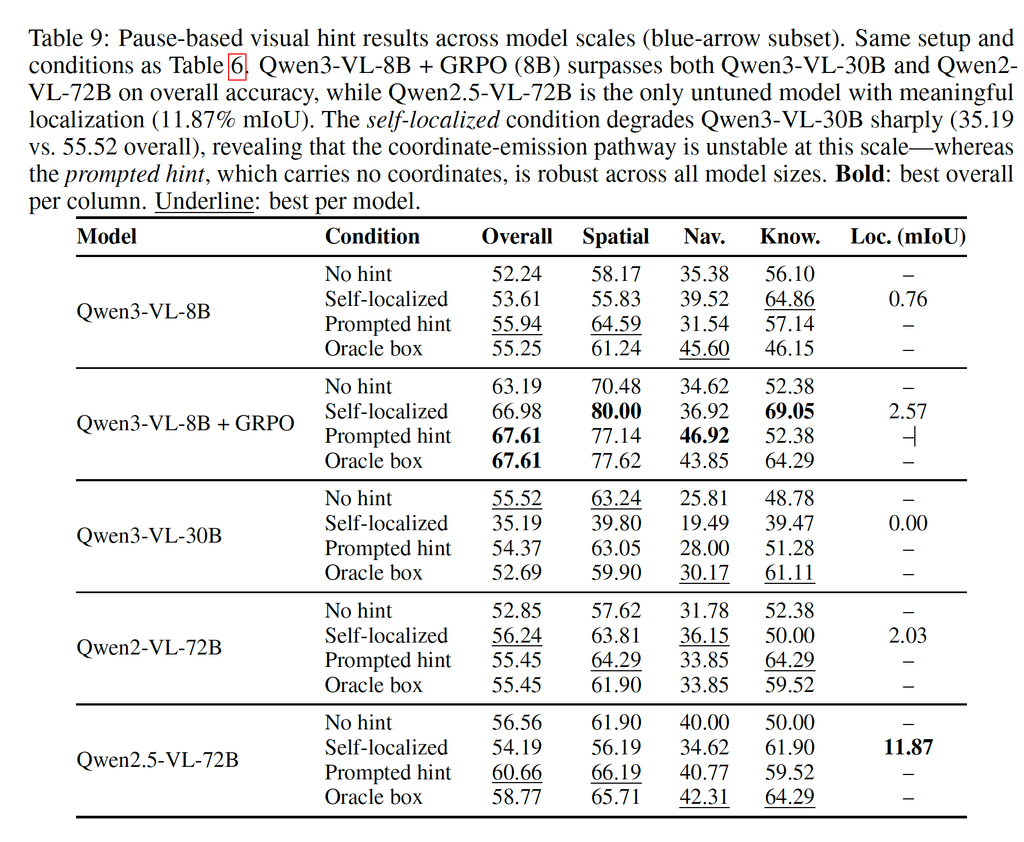
这份表格说明了几个问题:
- 直接给答案(oracle box)对于训练模型不是一件好事。还是要让模型自己多思考(self-Localized / Prompted hint);
- GRPO方法很奏效。
看这个方法对应的一个case分析:
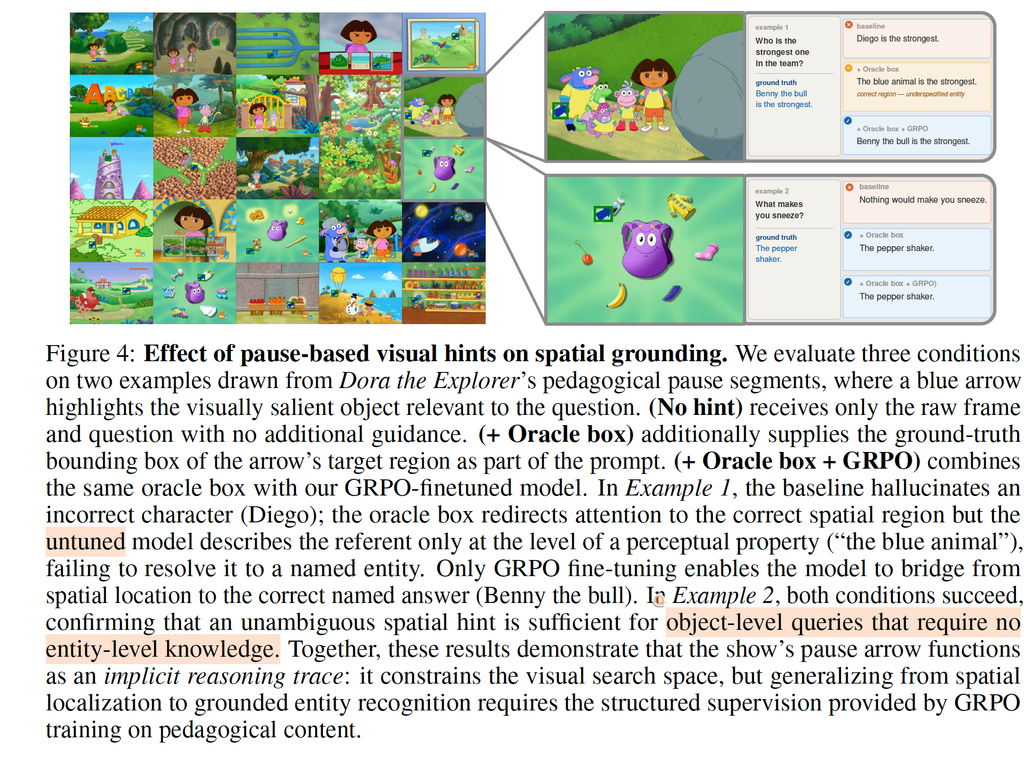
这篇论文的本质其实说明了两点:
- 在训练数据中添加显式的推理信息可以显著提升模型的推理能力;
- 善于从已有的数据(如视频)中得到精细化的(结构性)数据,进而提升模型的推理能力;
最后,这让我想起来,我们去年在训练交通标志牌数据的时候其实也是一样的思路:
问题:发现Qwen-2.5-72B 在交通标志上表现效果不好(尤其是对于人工指向性指令的识别不好);
解决方案:提出组合训练数据、通过箭头、顺序的方式提升模型的推理能力。
- [2025Nips] GRIT: Teaching MLLMs to Think with Images https://openreview.net/pdf?id=RW3cHh3HgY
- [2025Nips] Reason-RFT: https://proceedings.neurips.cc/paper_files/paper/2025/file/08d70284b013c03ba89cd2b642bc864b-Paper-Conference.pdf
- [ACL 2026] Forest Before Trees: Latent Superposition for Efficient Visual Reasoning https://arxiv.org/pdf/2601.06803
- [ACL 2026] Interleaved Latent Visual Reasoning with Selective Perceptual Modeling https://arxiv.org/pdf/2512.05665
- [MM 2026] Reinforcing Multimodal Reasoning via Token-Level Perception-Grounded Advantage Estimation https://arxiv.org/pdf/2609.39168
- Reactivating Test-Time Scaling for Plane Geometry Problem Solving https://arxiv.org/pdf/2608.30156
- [2026 arxiv] Optical Reasoning: Rethinking Images as an Expressive Reasoning Medium Beyond Text
- [2026 arxiv] DyCo-RL: Dynamic Cross-Modal Coordination for Visual Reasoning
Virgin Place
[] MM-OPD:Towards One More Bottleneck Between Perception and Reasoning https://arxiv.org/pdf/2609.32690
分析、溯源
- [2026 Nips] What’s Holding Back Latent Visual Reasoning https://arxiv.org/pdf/2605.18445
- [2026 Nips] STEMBIND: When MLLMs Get Lost Between Rules and Instances in Abstract Visual Reasoning: https://arxiv.org/pdf/2606.00148
- 【Nips 2026】Visual Latents Know More Than They Say: Unsilencing Latent Reasoning in MLLMs https://arxiv.org/pdf/2605.02735v1
- [Nips 2026] What MLLMs Learn about When they Learn about Multimodal Reasoning
https://arxiv.org/abs/2510.01719
能力迁移
- [2025Nips] Can MLLMs absorb Math Reasoning Abilities from LLMs as Free Lunch? https://openreview.net/pdf?id=tJhJYcCABr
其它
自博弈强化学习(self-play reinforcement learning)
与这个话题相关的pape有:
- https://arxiv.org/abs/2605.24794
- Meta AI
- 不过感觉这篇paper比较水?
- https://www.nature.com/articles/s41467-026-74579-8
- 这篇paper是研究在医学(病灶处理)上
研究点:
- Cross-Image Relation Reasoning
发表回复